Z-Image Turbo
Livez-image-turboimage.generate
Fast text-to-image. Up to 4 images per request (num_outputs), PNG, JPEG or WebP.
- Takes
- Prompt
- Returns
- 1 to 4 images
- Tiers
- 1k
- Licence
- Apache-2.0
- From
- $0.004 per image (0.08 credits)
Two image models are live today, z-image-turbo and flux-2-klein-4b, both open-source (Apache-2.0) with a fixed price per output. No video model is live yet. The rest are open-source and open-weight models we don't serve yet. Request early access to start with the live ones.
Two models you can call today, each with a fixed price per output. Every picture is a real output, labelled with its prompt, model and seed.
Livez-image-turboimage.generate
Fast text-to-image. Up to 4 images per request (num_outputs), PNG, JPEG or WebP.
Liveflux-2-klein-4bimage.generate
The smallest FLUX.2 model, a 4-step distilled 4B text-to-image model. Up to 4 images per request (num_outputs), PNG, JPEG or WebP.
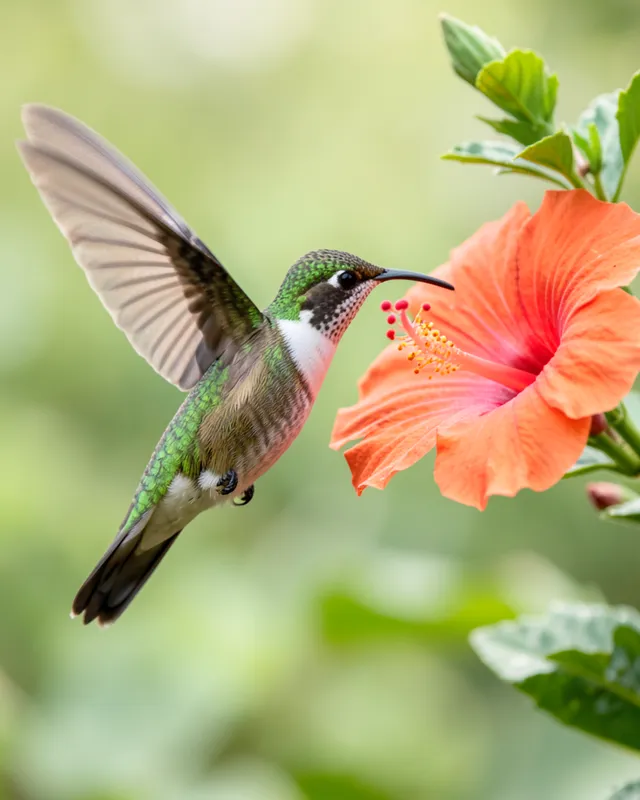
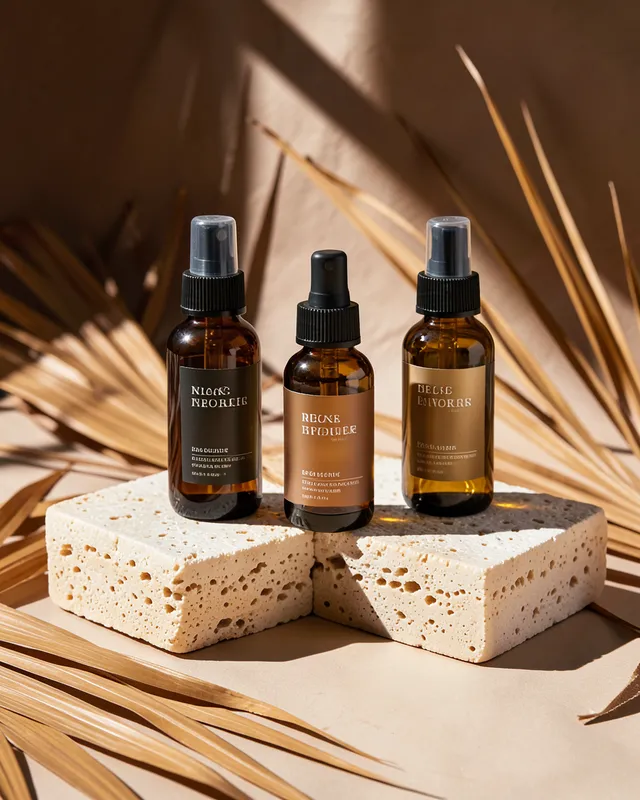
2 are live and priced per output. 6 more are coming soon: models Windpaint doesn't serve yet, listed with their licence and specs but no price. 3 more are listed for reference.
Livez-image-turboimage.generate
Fast text-to-image. Up to 4 images per request (num_outputs), PNG, JPEG or WebP.
Liveflux-2-klein-4bimage.generate
The smallest FLUX.2 model, a 4-step distilled 4B text-to-image model. Up to 4 images per request (num_outputs), PNG, JPEG or WebP.
Coming soon
The undistilled base of the Z-Image family, meant for fine-tuning and LoRA training.
Coming soon
The December 2025 update of Qwen-Image, a 20B text-to-image model built for rendering text in images.
Coming soon
The few-step, Apache-2.0 member of the FLUX.1 family, with a large ecosystem of tools and fine-tunes.
Coming soon
An 8B model that works on raw pixels and does text-to-image, editing and subject personalization up to 2048 × 2048.
Coming soon
SDXL 1.0 base, the latent diffusion model with a large library of community LoRAs and ControlNets.
Reference
The larger FLUX.2 [klein] model: text-to-image and multi-reference editing in one 9B model, step-distilled to 4 steps, under a non-commercial licence.
Reference
A 7B Qwen-Image release that combines text-to-image, editing with up to 10 references and transparent RGBA output, under a research-only licence.
Reference
A 33.1B image model derived from MiniMax H3, doing text to image, up to 16 references and editing at about 16 MP in 6 steps.
Coming soon
Instruction-based image editing on the 20B Qwen-Image model, with one or more input images.
0 are live and priced per output. 5 more are coming soon: models Windpaint doesn't serve yet, listed with their licence and specs but no price. 3 more are listed for reference.
Coming soon
Wan2.2-T2V-A14B makes 5 second clips at 480p or 720p from a prompt alone.
Coming soon
The small Wan 2.2 model: text-to-video and image-to-video at 720p, 24 fps, in one 5B model.
Coming soon
A 13.6B model for text-to-video, image-to-video and video continuation, built for long clips.
Coming soon
Tencent's 8.3B video model for text-to-video and image-to-video, sized for a single GPU.
Reference
Lightricks' 22B audio-video model, with native multishot generation, a Gemma 4 text encoder and an optional duration predictor.
Reference
Lightricks' 22B audio-video model from March 2026, with dev and 8-step distilled checkpoints and a LoRA trainer.
Reference
MiniMax's 33B omni video model, generating video with native stereo audio from text, first and last frames or mixed references, at 768p when self-hosted.
Coming soon
Image-to-video. It animates a start frame you supply.
Prices are in credits per output. One credit costs $0.05. Aspect ratio and output format don't change the price, and you're charged only for outputs delivered.
| Model | Capability | Tier | Credits | USD |
|---|---|---|---|---|
z-image-turbo | image.generate | 1k 1024 px long edge | 0.08 per image | $0.004 |
flux-2-klein-4b | image.generate | 1k 1024 px long edge | 0.1 per image | $0.005 |
You submit to a capability such as image.generate. A model implements it, and you can name one or let Windpaint pick.
Send POST /v1/generation/capabilities/image.generate with a prompt. Add model to choose one, or leave it out and the capability's first available model runs. The job status reports which model ran.
A resolution tier sets one edge and the aspect ratio sets the other. Image tiers set the long edge, video tiers the short edge. All 10 ratios work on every live model.
The estimate is held from your balance and captured when the job completes. Failed, refused and canceled jobs release it. A list price change never touches a job already sent.
If Windpaint updates what's behind z-image-turbo, requests that name it get the update. Pair a fixed seed with a versioned preset when you need repeatable output.
The catalog endpoint is the source of truth for what's live and what it costs. Read prices and tiers from it rather than hard-coding them.
# Capabilities, their input slots, and each model's tiers and pricescurl https://api.windpaint.ai/v1/generation/capabilities \ -H "Authorization: Bearer $WINDPAINT_API_KEY"# The same data organized by modelcurl https://api.windpaint.ai/v1/generation/models \ -H "Authorization: Bearer $WINDPAINT_API_KEY"Each model entry carries available, prices (one row per tier, credits as decimal strings), resolutions, durations, max_outputs, output_formats and licence. POST /v1/generation/estimate validates a request like submit does and returns its price and pixel size without creating a job.
These capabilities are part of the API's schema and appear in the catalog with an empty model list. Submitting to one returns 422. None has a date.
| Capability | Inputs | Output | Status |
|---|---|---|---|
image.edit | 1 to 3 images, optional mask | image | No model, returns 422 |
mask.segment | 1 image | mask | No model, returns 422 |
media.upscale | 1 image or video | same as input | No model, returns 422 |
audio.speech | text, optional voice sample | audio | No model, returns 422 |
video.lipsync | 1 image or video, 1 audio | video | No model, returns 422 |
text.llm | 0 to 8 images | text | No model, returns 422 |
The capability's first available model in catalog order, so image.generate runs z-image-turbo. Send model: flux-2-klein-4b to use the other image model. If more models ship, the default can change, so name the model when you need a specific one. The job status always reports which model ran.
No. Model ids are stable slugs, and if Windpaint updates what's behind a slug, requests that name it get the update. Prices are fixed per job when you submit, so a price change never affects a job you've already sent.
The live ones are. Both are licensed Apache-2.0, an OSI-approved open-source licence. Some coming-soon models are open-weight instead: the weights are public, but the licence restricts use. The catalog endpoint returns each model's licence, so you can check it from code.
On Windpaint's own GPUs. Your prompts and inputs are not sent to a third-party model API to generate these outputs, and Windpaint does not train on your prompts, inputs or outputs.
A coming-soon model is one Windpaint doesn't serve yet. Its page has the licence and specs from the model's own card, but no model id or price, and you can't call it. None has a date. Request early access to get in while we add them.
Those capabilities are defined in the API schema and appear in the catalog with no models. Submitting to one returns 422. Qwen-Image-Edit-2511 is listed as coming soon for image editing. There's no date attached to any of them.
Call GET /v1/generation/capabilities. Each model carries a prices array with one row per tier, and credit amounts are decimal strings. POST /v1/generation/estimate prices a specific request and returns the output size without running it.
Request early access. We’ll email you when your account is approved, with 200 free credits to spend in the first 30 days.